The gold standard for
correcting AI mistakes
The most accurate detection and correction layer on the market — the only one that actually fixes hallucinations, so your customers never see an unsafe or incorrect AI response again.
Last updated 02:27:56 PM CDT
Built by teams from
Don't take our word for it. The numbers speak.
Head-to-head against AWS Bedrock Guardrails on real-world evaluation benchmarks, DeepRails outperforms across every metric.
The DeepRails Suite
See How It Works
DeepRails gives you three tools — pick the one you need. Defend catches and fixes hallucinations before customers see them. Monitor tracks quality across your entire AI stack. Playground lets you try it all — free, no code required.
Defend API
Your real-time AI correction engine.
Automatically detects low-quality or hallucinated outputs and fixes them with ReGen or FixIt, so only safe, accurate answers reach your customers.
Configure a Workflow
Set up guardrail metrics, hallucination thresholds, and improvement actions in minutes
Detect & Fix Hallucinations
Automatically identify quality issues and fix them with FixIt or ReGen before they reach customers
View Analytics in Console
Track performance metrics, improvement chains, and drill into any run for full audit details
.png)
Your LLM
Defend API
Customer
Defend scores model output
console.deeprails.com/analyticsLive PreviewWhat you'll see in the console — real-time metrics, audit logs, and full observability across every API call.
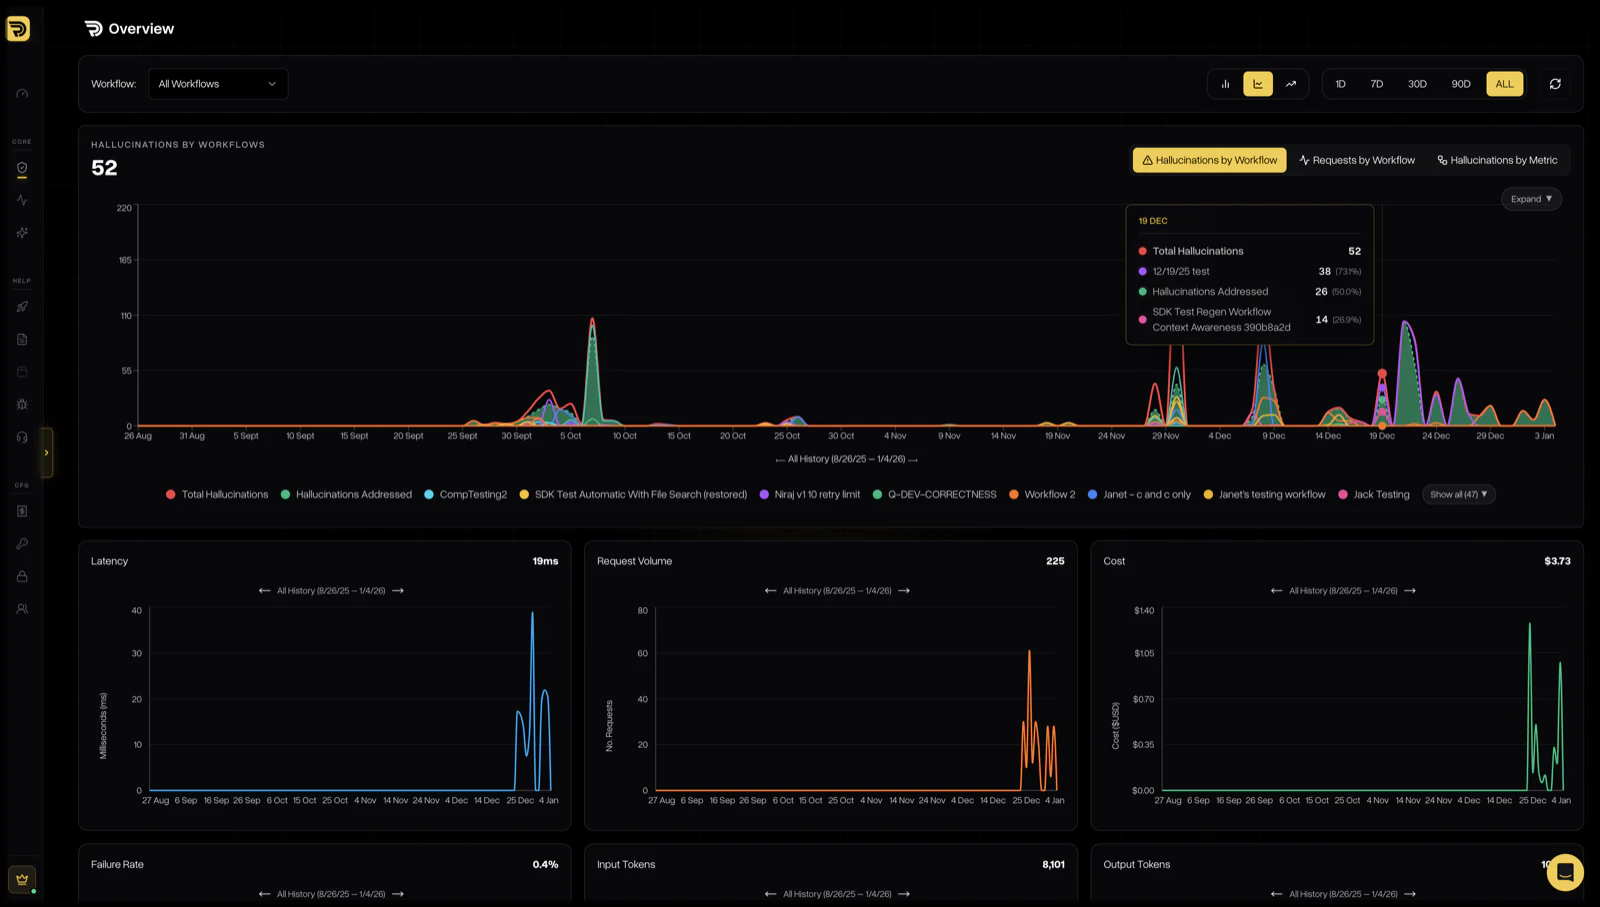
Hallucinations caught, fixed, and key metrics
01/03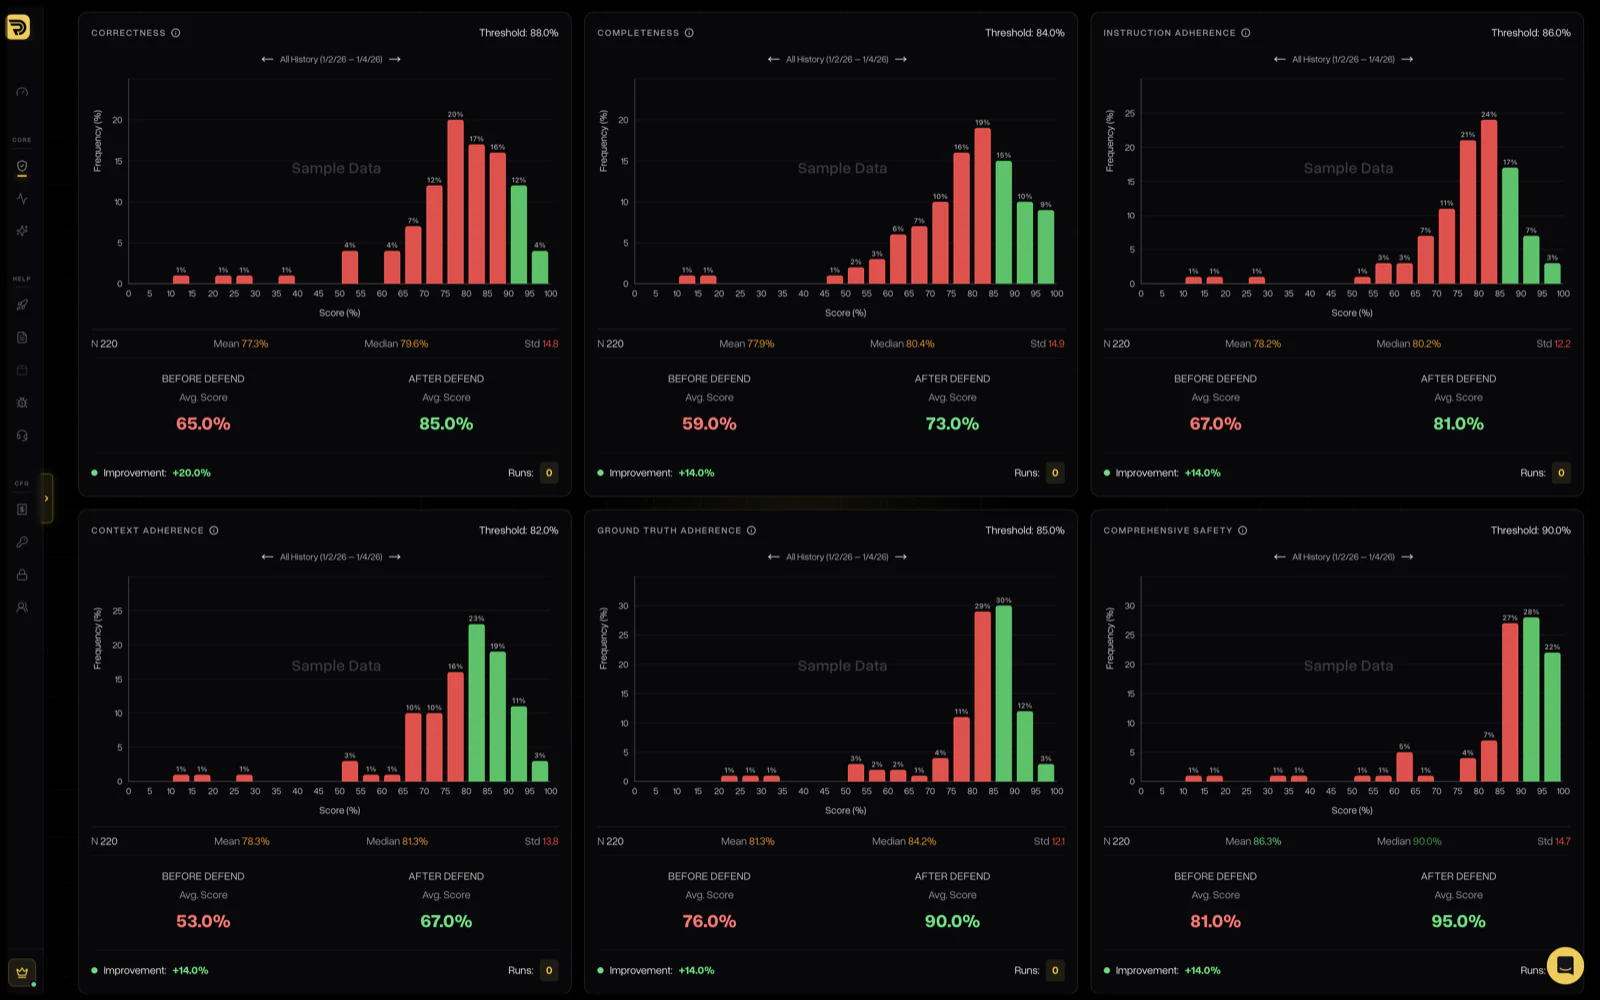
Correctness, completeness, safety distributions
02/03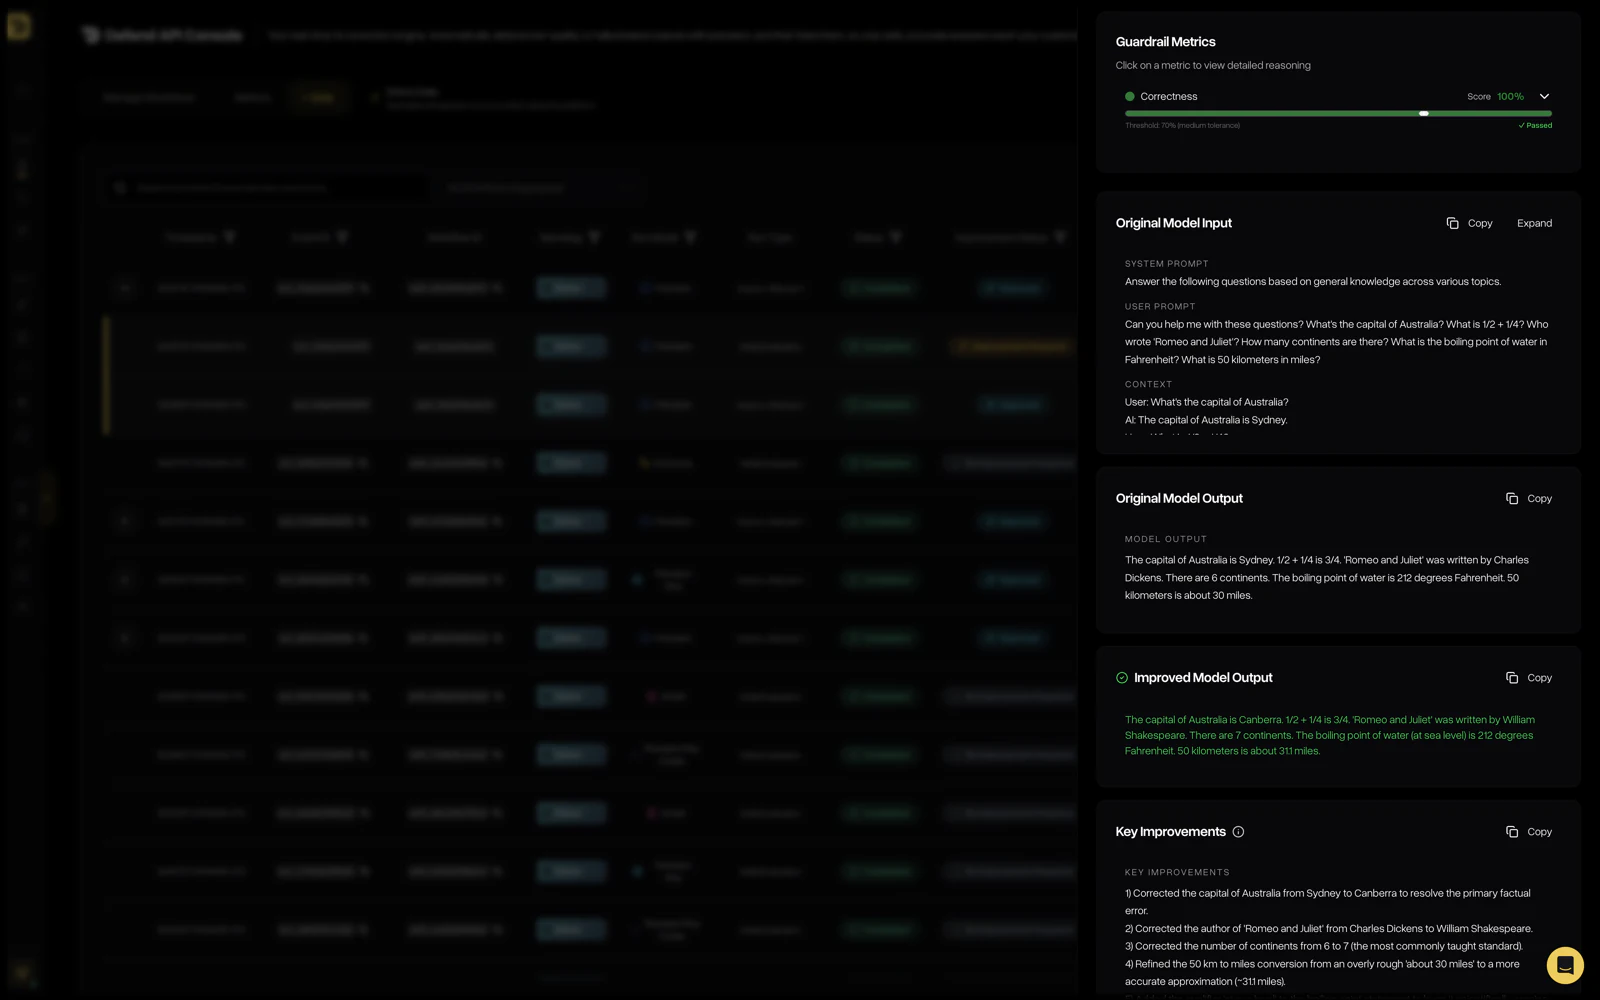
Run history, improvement chains, full trace
03/03Built for Engineers
Full Developer
Configurability
Every parameter is in your hands. Configure Workflows for Defend and Monitors for Monitor — from run modes to adaptive thresholds, everything bends to your requirements.
Configure Once, Deploy Everywhere
Define your workflow once and roll it out across Defend and Monitor — the same config powers prod, staging, and every service
Support Chatbots
wkfl_support_botsGuardrail Metrics
Web Search
Extended AI Capability
Website Chatbot
Website Chatbot
Mobile App Chat
Slack Support Bot
Each app just references the same workflow_id
6 Powerful Run Modes
From Super Fast to Precision Max Codex — choose the accuracy/cost tradeoff that fits your use case
Higher run modes provide deeper verification at increased compute cost
Hallucination Tolerance Thresholds
Choose Automatic thresholds powered by DeepRails adaptive algorithms, or set Custom values per metric when you need total control
Automatic Thresholds
DeepRails adaptive algorithms auto-calibrate your tolerance based on real workflow performance — recommended for most teams
Finance, medical, education, legal
Internal tools, content drafts, research
Creative content, brainstorming
Adaptive Learning
Your workflow continuously learns and adapts its quality thresholds based on real performance data. The more your workflow processes outputs, the smarter it becomes at distinguishing acceptable outputs from hallucinations.
After 25+ runs, thresholds begin adapting to your workflow's unique patterns
Custom Thresholds
Advanced teams can set precise threshold values (0-100%) for each metric based on exact requirements
Outputs scoring below your thresholds trigger improvement actions
Choose Your Improvement Tool
Define how the system responds when outputs fail your thresholds
Maximum Improvement Attempts
Configure how many improvement cycles to run until outputs pass all thresholds (default: 10, max: 100)
Extended AI Capabilities
Supercharge your evaluations with real-time web access and RAG-powered file search
Web Search
Real-timeAllow the AI to search the web for up-to-date information during evaluation and improvement
File Search
RAGEnable AI to search and analyze your uploaded documents for context-rich evaluations
Context Awareness
EnhancedLeverage additional context from your inputs for smarter, more nuanced evaluation
Expansive Library ofGuardrail Metrics
Choose from general-purpose metrics or create custom metrics tailored to your domain—each one precisely detecting whether hallucinations exist in your AI outputs with granular 0-100 scores.
Correctness
Is it factually accurate?
Evaluates whether each claim in the AI output is true and verifiable—critical for healthcare, finance, and legal domains.
Completeness
Did it answer everything?
Assesses whether the response addresses all parts of the prompt with sufficient detail and relevance.
Instruction Adherence
Did it follow the rules?
Checks whether the AI followed explicit instructions including tone, structure, format, and style guidance.
Context Adherence
Did it use the provided context?
Determines whether each factual claim is directly supported by the provided context—essential for RAG systems.
Ground Truth Adherence
Does it match the gold standard?
Measures how closely the output matches a provided correct answer—ideal for benchmarking and fine-tuning.
Comprehensive Safety
Is it safe to deliver?
Detects PII, hate speech, self-harm content, prompt injections, CBRN, and other safety violations.
Agentic Performance
How effective is the agent?
Evaluates how effectively the AI autonomously plans, decides, and executes complex multi-step tasks.
Tool Call Correctness
Are tool calls valid?
Validates that AI tool calls are accurate and properly formatted—essential for agentic workflows.
More Metrics
General-purpose guardrails
We're building more general-purpose metrics to help you evaluate and improve AI outputs across a wider range of use cases.
Custom Metrics
Two ways to add bespoke guardrails
Register your own prompt-based metric or purchase a fully built, guaranteed metric from our engineers—both available on Pro and Enterprise plans.
Register your own metric
Self-serve • Bring your prompt
Add domain-specific checks instantly with your evaluation and fix prompts. Perfect for rapid experimentation across Detect, Score & Fix flows.
Purchase a custom metric
Built-for-you • Guaranteed performance
Partner with DeepRails engineers to design, test, and stand up a production-grade metric with accuracy guarantees—ideal for regulated or high-stakes workloads.
Earn the Trust Badge
Your AI Deserves
SSL secured the web — Hallucination Safe™ secures AI
Just as the padlock icon became the universal trust signal for secure websites, the Hallucination-Safe™ Seal is the new standard for AI you can rely on. It's awarded exclusively to systems protected by DeepRails' Defend API — every output evaluated, corrected, and verified.
The trust signal for the AI era
Hallucinations erode trust and create compliance, reputational, and financial risk. The Hallucination-Safe™ Seal tells your customers, partners, and regulators that your AI is guarded, transparent, and dependable — the same assurance SSL gave to online transactions.
Case Studies
See how companies are using DeepRails to build reliable AI products.
Latest insights
Technical research on AI safety, evaluation frameworks, and production guardrails.
Ready to ship AI your customers can trust?
Start for free. No credit card required. Get hallucination detection and correction running in under 5 minutes with our SDKs for Python, TypeScript, Go, and Ruby.